Hybrid RAG
Combine lexical and vector rankings while preserving source content; an executable fusion example and explicit evaluation boundaries.
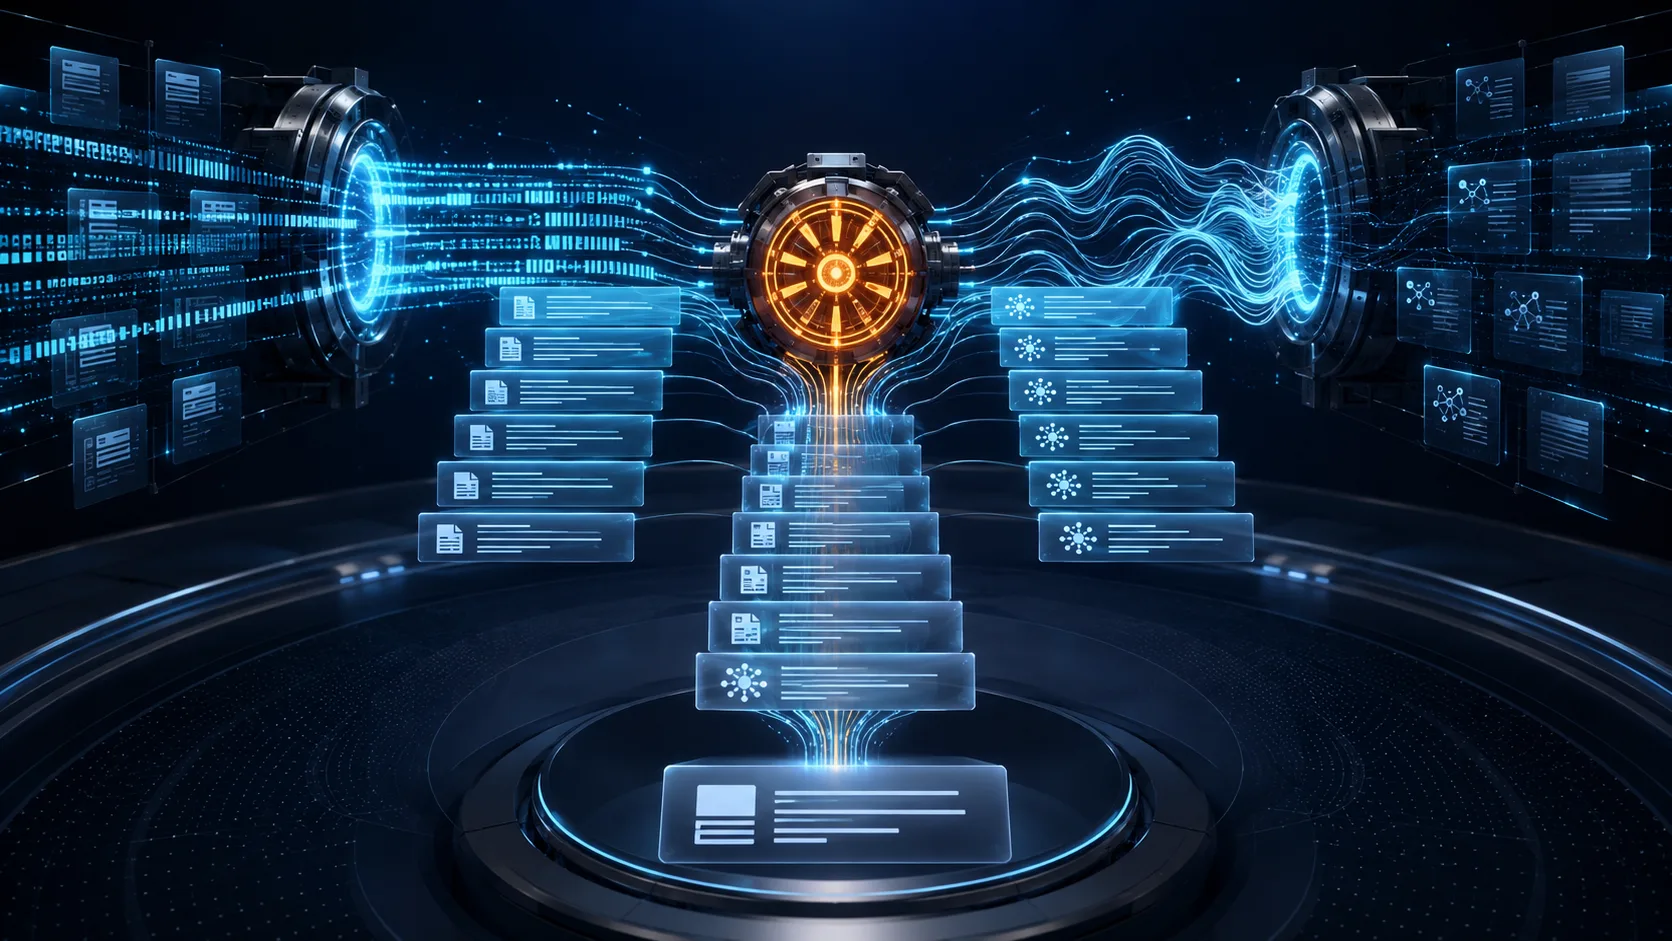
A search for an exact error code and a search for “why does sign-in keep failing?” ask different things of a retriever. Lexical search can reward the exact identifier. Vector search can find related language even when the words differ. Hybrid retrieval combines those signals.
Two rankings, one candidate list
BM25 ranks lexical matches using term statistics and document length. Vector retrieval ranks similarity under an embedding model. Neither guarantees relevance: lexical search can miss paraphrases, while a nearby vector may describe the wrong product or version.
Reciprocal rank fusion (RRF) combines ranks rather than treating incomparable raw scores as interchangeable. For each document, add 1 / (k + rank) across the ranked lists in which it appears. Ranks start at 1. The constant controls how much top positions dominate. This example uses unweighted RRF with k=60; it has no separate alpha parameter. Elasticsearch’s RRF definition.
A runnable example
The following Python example uses fictional documents and manually supplied rankings. It tests fusion and content handling, not retrieval quality or a cloud deployment.
from collections import defaultdict


def reciprocal_rank_fusion(rankings, documents, k=60):
    if k <= 0:
        raise ValueError("k must be positive")
    scores = defaultdict(float)
    for ranking in rankings:
        seen = set()
        for rank, chunk_id in enumerate(ranking, start=1):
            if chunk_id in seen:
                continue
            if chunk_id not in documents:
                raise KeyError(f"Missing authorized document: {chunk_id}")
            seen.add(chunk_id)
            scores[chunk_id] += 1.0 / (k + rank)
    ordered = sorted(scores, key=lambda key: (-scores[key], key))
    return [
        {**documents[key], "chunk_id": key, "rrf_score": scores[key]}
        for key in ordered
    ]


documents = {
    "a": {"content": "ERR-42 means the session token has expired.",
          "source": "Auth manual, version 2, section 4"},
    "b": {"content": "Renew an expired session by signing in again.",
          "source": "Support guide, version 3, section 2"},
    "c": {"content": "A network timeout can interrupt sign-in.",
          "source": "Network guide, version 1, section 6"},
}
lexical = ["a", "b"]
semantic = ["b", "c", "a"]
rrf_results = reciprocal_rank_fusion([lexical, semantic], documents)
context = "\n\n".join(
    f"[{chunk['chunk_id']}] {chunk['content']} ({chunk['source']})"
    for chunk in rrf_results[:3]
)
print(context)
The returned objects retain content and provenance. Returning only (id, score) tuples and later reading chunk['content'] would fail. In a real service, both rankings and the document lookup must already be restricted to the caller’s authorized corpus; recheck permissions before returning an answer.
Passing context to a model
A model API call is a separate integration. For Amazon Bedrock, the documented Converse request uses messages with content blocks and inferenceConfig. A generic prompt/max_tokens JSON body is not a portable native request for every model. Use a supported model or inference profile in the selected region and follow the Bedrock Converse API. The fusion example above deliberately ends at the context string so it can run without credentials or a live service.
Treat retrieved documents as untrusted evidence. A document telling the model to ignore its instructions is not an instruction from the user. Keep tool permissions separate from document text, require citations, and test adversarial passages as well as ordinary search questions.
Is the extra retrieval path worth it?
Compare lexical-only, vector-only, and fused retrieval on the same held-out questions. Include exact identifiers, paraphrases, version-sensitive questions, and questions the corpus cannot answer. Measure retrieval recall and ranking quality separately from final answer support.
Keep model, corpus, authorization rules, and context budget consistent. If you add reranking at the same time as hybrid retrieval, you cannot attribute the full gain to fusion alone. Record latency and cost for both retrievers, the merge, any reranker, and generation, including retries.
A hypothetical result might show better exact-code retrieval but little improvement for conceptual questions. That would justify routing or targeted hybrid use, not a universal accuracy claim. There is no fixed enterprise precision range or customer ROI established by this example.
Hybrid retrieval is an option to test when complementary signals address observed failures. Its value comes from returning better evidence for your questions, not from having two search engines on the diagram.
Continue in