Naive RAG
Understand the simplest retrieve-and-generate pipeline through a small fictional corpus, its failure modes, and a practical evaluation plan.
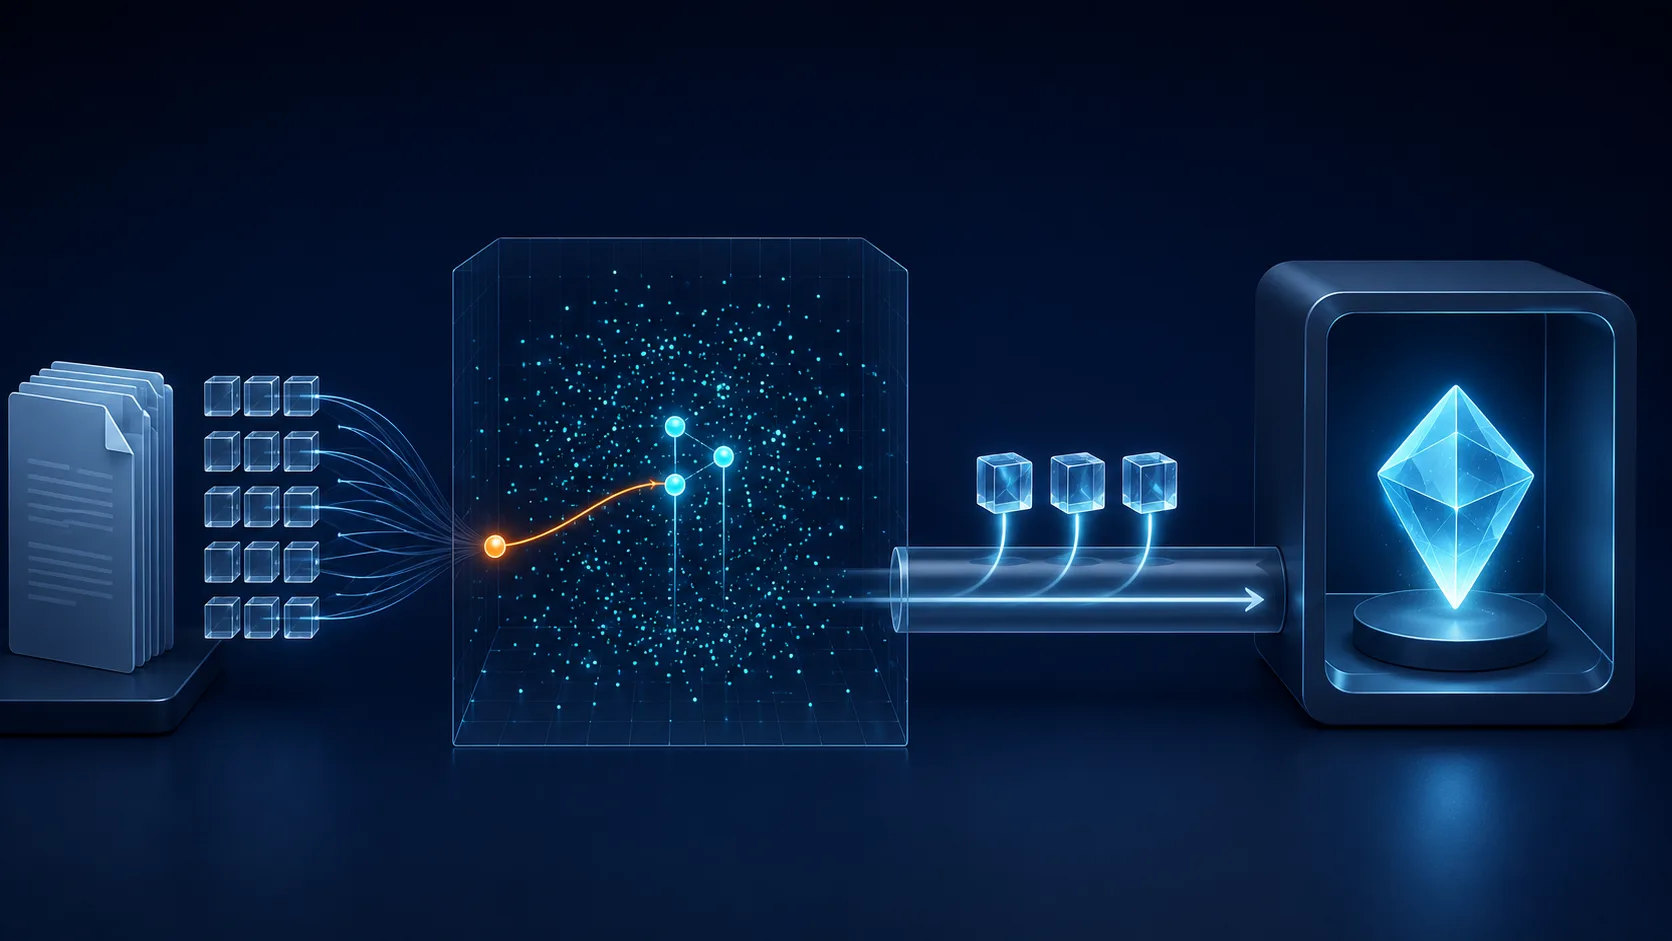
Naive RAG is the simplest form of retrieval-augmented generation: embed the documents, find the closest few, and hand them to a model with the question. Its limits are a useful map of what more elaborate techniques are trying to fix.
That is worth understanding before adding complexity. A small, well-scoped corpus may not need a graph, a reranker, or several agents.
The basic mechanism
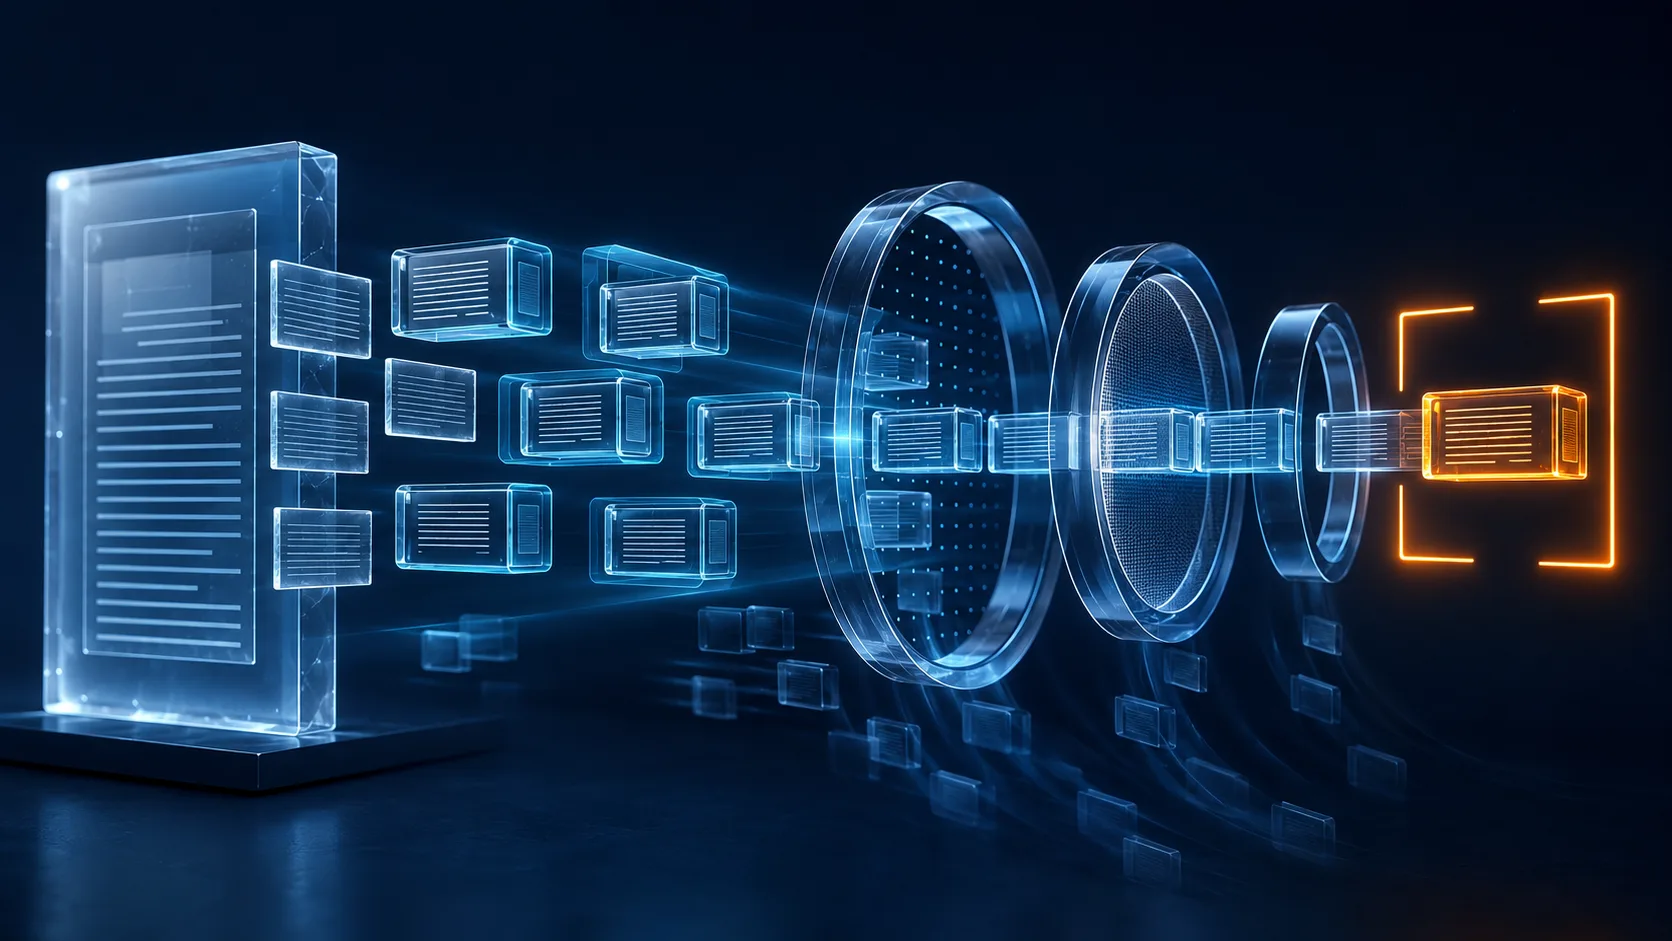
During indexing, split source documents into passages, calculate an embedding for each, and retain source identifiers, versions, and access metadata. At query time, embed the question with a compatible model, retrieve nearby passages, and ask a generator to answer using that evidence.
An embedding is a vector representation, not a guarantee that two passages mean the same thing. Cosine similarity divides the dot product by the product of vector lengths; for nonzero real vectors its mathematical range is −1 to 1. Dot product can also rank vectors, but it is affected by magnitude. For unit-normalized vectors, dot product equals cosine similarity. Choose the metric your embedding model and index support. Sentence Transformers’ similarity documentation.
Three questions reveal more than a success story
Consider this fictional support corpus:
| Source | Passage |
|---|---|
| Account guide v2 | Reset a forgotten password using the recovery email. |
| API guide v3 | Error Q17 indicates that the API token has expired. |
| Billing policy v1 | Annual plans renew on the anniversary of purchase. |
A likely success: “How can I get back into my account if I forgot my password?” A semantic match to the account guide gives the generator relevant evidence. Inspect the answer and citation rather than assuming the match guarantees correctness.
A retrieval miss: “What does Q17 mean?” An embedding may not give an unfamiliar identifier enough weight. Test whether lexical search helps before adopting a more complex architecture.
An unsupported question: “Can I get a refund after renewal?” None of these passages defines a refund policy. A fluent answer would still be unsupported. The desired behavior is to say the available documents do not establish the policy and direct the user to an appropriate source.
These are illustrative cases, not measured success rates. The exact retrieved order depends on the model, chunking, index, and corpus.
Where it breaks
Chunking can separate a rule from its exceptions. Old and new policies can look similar. The right passage may be outside the top results. The generator may misuse good evidence or obey malicious text within it. Access filters may omit a required restriction. These are different failure modes and need different remedies.
Preserve source boundaries and version metadata first. Evaluate lexical retrieval for identifiers, contextual enrichment for ambiguous chunks, and graph traversal for explicitly modeled relationships. Adding generated document context makes the pipeline contextual RAG; it should no longer be reported as an unchanged naive baseline.
What a responsible trial reports
Build a held-out question set with source passages and expected behavior, including missing answers and unauthorized documents. Report how examples were selected and reviewed. Evaluate retrieval separately from generation so a failure can be located.
Track citation correctness, supported answers, abstention, and access isolation alongside latency and spend. Specify whether latency means first token or complete answer and include percentiles; a component timing is not end-to-end response time. Cost includes indexing, model input and output, storage, retrieval capacity, retries, and operational work. No universal sub-200ms response time or fixed per-query price follows from this architecture.
Keep the first version simple
A useful first system retrieves evidence, shows its source, and makes failures visible. It should have a defined audience, a bounded task, and a way for the user to challenge the answer. A reference architecture alone is not a production-readiness result.
Start there. Add another mechanism when the evaluation gives it a specific problem to solve.
Continue in