What Is RAG?
A practical introduction to retrieval-augmented generation: how evidence reaches a model, how it can fail, and what to check.
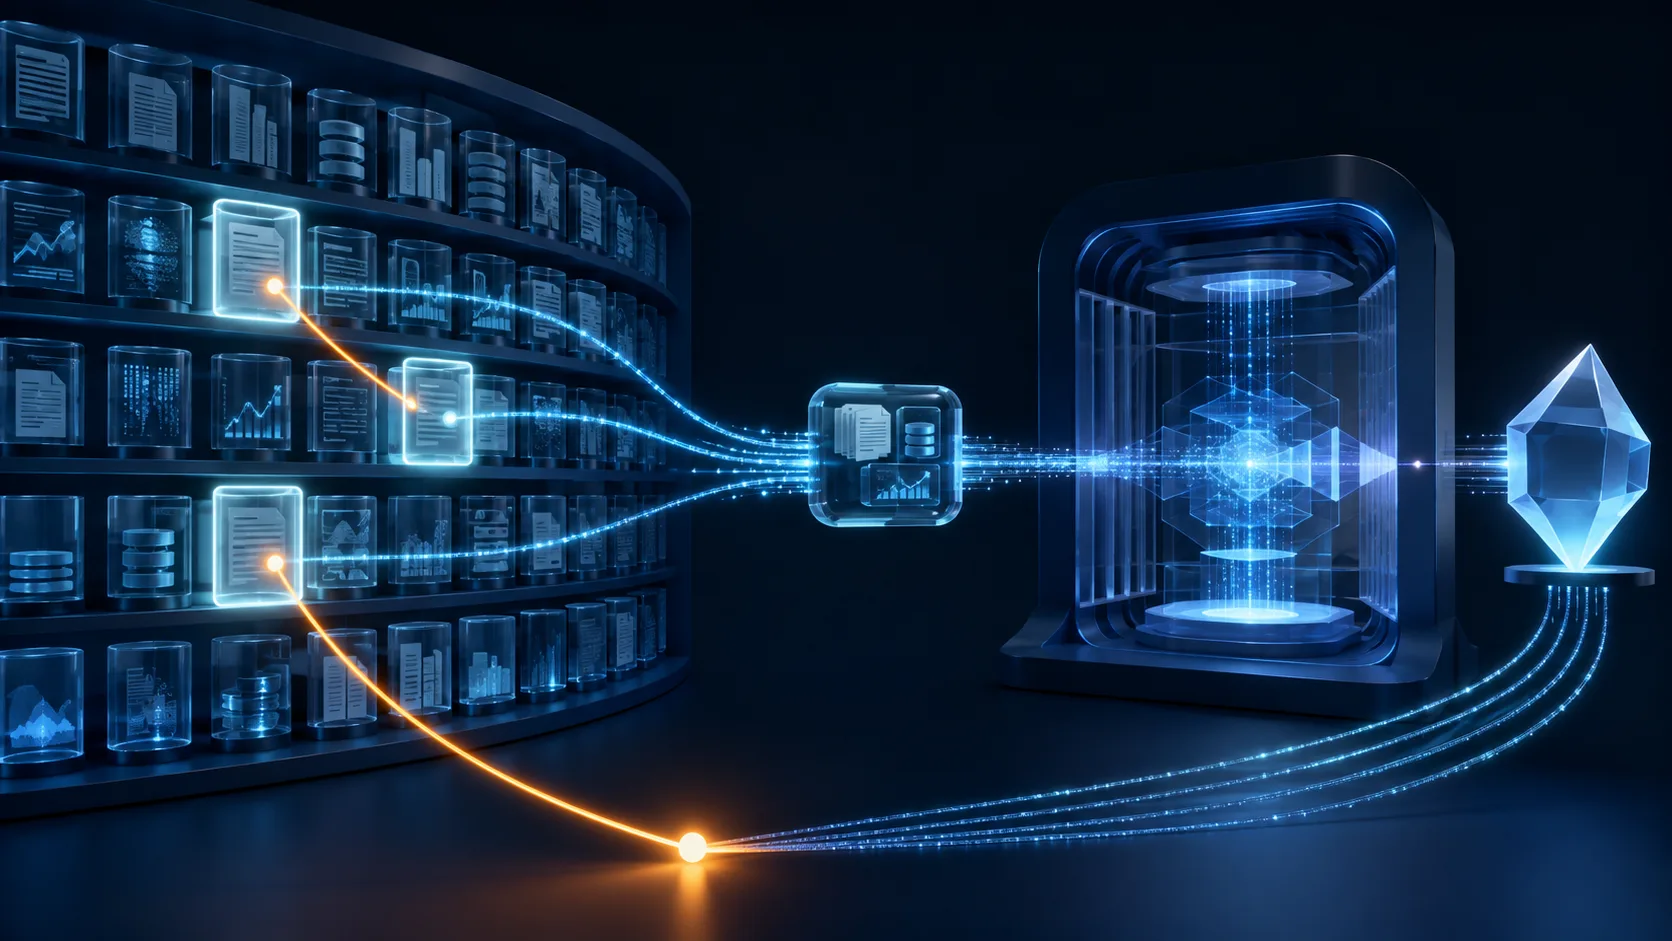
Imagine asking a librarian a question and receiving both an explanation and the pages used to answer it. Retrieval-augmented generation, or RAG, tries to give a language model a similar starting point: relevant source material supplied at the time of the question.
The model still writes the answer. Retrieval changes what evidence is available to it.
Retrieve, augment, generate
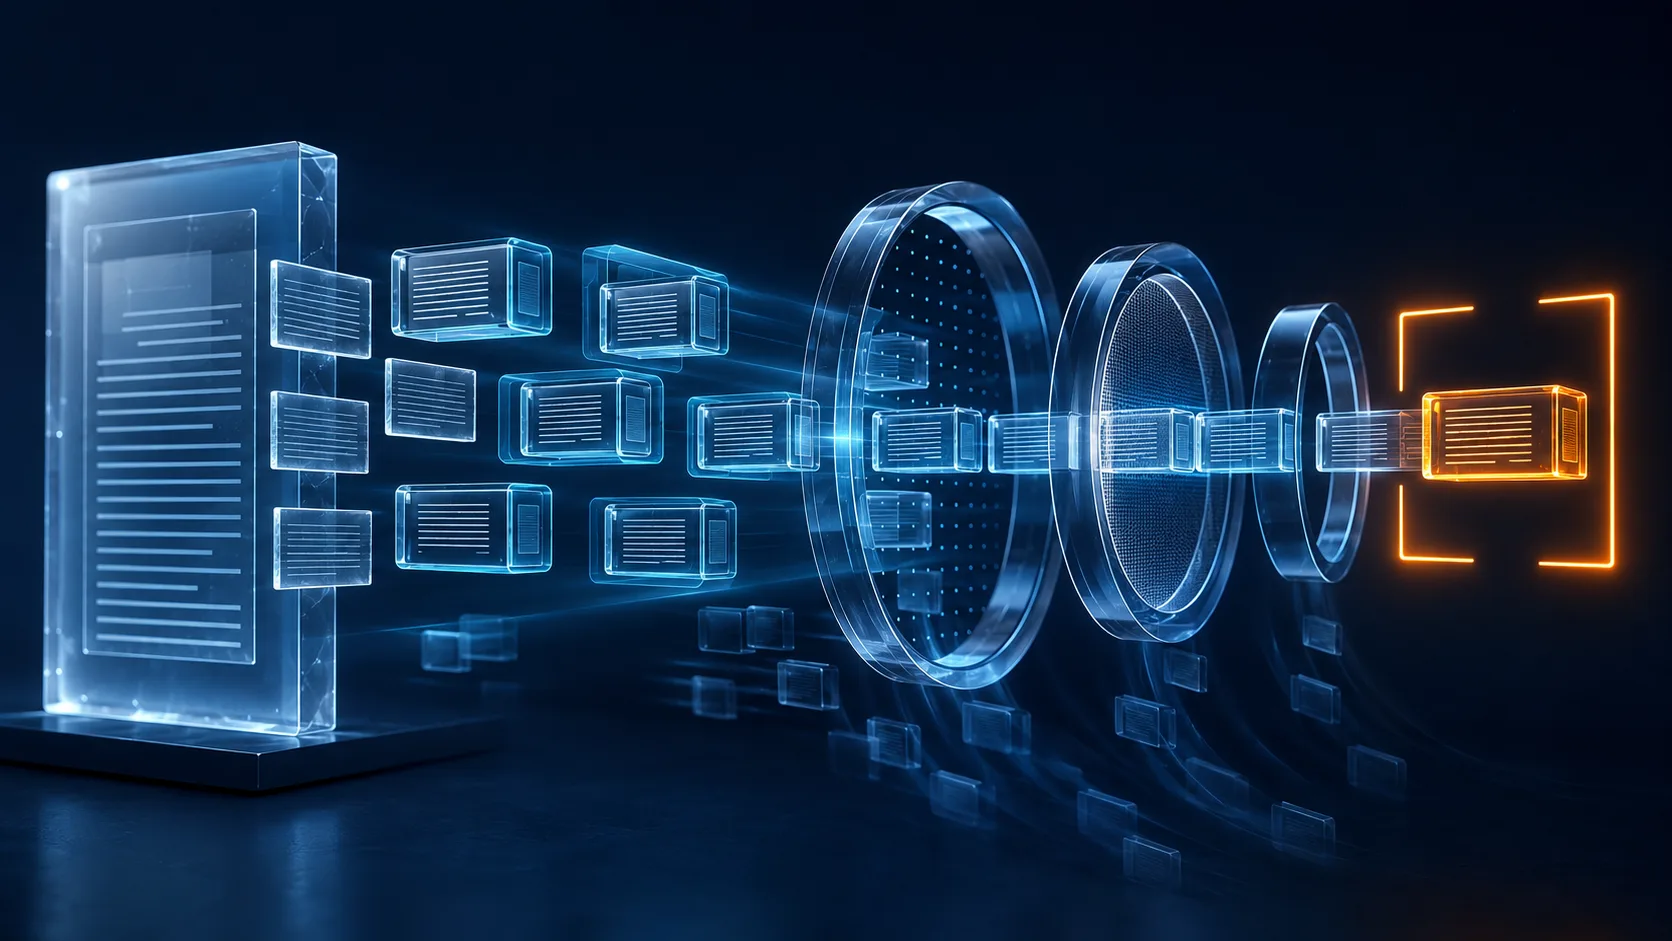
A typical system has two phases. First it prepares a searchable collection of documents, preserving source locations and access permissions. Then, for each question, it retrieves relevant passages, puts them into the model’s input, and generates an answer.
Search may use words, vector similarity, or both. Vector embeddings represent text numerically so related passages can be found even when wording differs. Retrieval is not limited to vector databases; structured queries and other search tools can also supply evidence.
The original RAG research combined a pretrained generator with a retriever over an external index. Today’s applications use many variations on that principle. Lewis and colleagues, RAG paper.
A fictional policy example
Suppose an employee asks, “Can I carry unused leave into next year?” The search finds the current leave policy, including the carryover limit, eligibility conditions, and effective date. The generator explains the rule and points to that passage.
Now suppose the retriever finds last year’s policy instead. The answer can sound equally convincing while being wrong. Or it might find only the limit and miss an exception for the employee’s location. Better prose cannot repair missing evidence.
A useful system therefore preserves dates and versions, applies access rules, and gives readers a route back to the source. If the available material does not answer the question, saying so is a successful behavior.
RAG, model knowledge, and fine-tuning
A base model’s training knowledge and a product’s access to search or tools are different things. A model with an older training cutoff can still be given a new document. Conversely, a tool-enabled product can answer incorrectly if it retrieves the wrong material.
Fine-tuning changes model parameters; retrieval supplies information at inference time. Fine-tuning can help with behavior or specialized tasks, while RAG can make changing source material available without retraining the generator. The approaches can be combined. Neither has a universal cost, and fine-tuning is not always a six-figure project.
What retrieval improves—and what it does not establish
Retrieval can help with freshness, source visibility, and access to a particular corpus. It does not guarantee that an answer is true, that citations support every sentence, or that documents themselves are accurate. A generated answer may invent a claim even when the correct evidence is present.
This article does not assign a general percentage reduction in hallucinations. Such a number needs a defined task, baseline, dataset, and evaluation method. A retrieval-recall improvement cannot be substituted for clinical accuracy or legal reliability.
The first checks I would make
- Does the system find the necessary evidence on representative questions?
- Does the final answer stay within what those sources support?
- Can a reader open the cited version and passage?
- Does the system decline questions the corpus cannot answer?
- Can one user retrieve another user’s restricted material?
- What happens when a source contains malicious instructions or conflicting information?
Use held-out cases, review failures, and record the model and corpus versions. For consequential decisions, add domain-specific validation, human review where appropriate, and a correction or escalation path. A firewall or content filter is one control; it does not certify the full application as safe.
What it takes to operate
The cost includes document processing, embeddings where used, storage, retrieval capacity, generator input and output, retries, and maintenance. Updating a document may require removing an obsolete version from several indexes. Deleting it from the original repository does not necessarily delete every cached copy.
Start with a bounded problem and a small evaluation set. Naive RAG explains the simplest vector pipeline. Hybrid RAG combines lexical and semantic search. Contextual RAG addresses ambiguous chunks, while Graph RAG makes selected relationships explicit.
The point is not to make an answer look well sourced. It is to make the evidence available, check how the model uses it, and keep the reader able to verify the result.
Continue in